Small-to-medium events do not need the biggest technology stack. They need one that is coherent.
That sounds obvious, but many event teams end up with a patchwork of tools chosen at different times for different reasons: ticketing in one place, speaker updates in another, sponsor files in a spreadsheet, check-in handled separately, and reporting stitched together after the fact.
The result is not always a lack of software. More often, it is a lack of operational continuity.
The recent industry conversation around bringing the whole event together is useful here. Even without assuming any one ideal platform model, the practical lesson is clear: event technology works best when the handoffs between tasks are predictable.
A good event tech stack is not the one with the most features. It is the one your team can run confidently during a busy event week.
Why this matters for event operations
For small-to-medium events, the stack decision is rarely abstract. It affects whether the team can launch on time, answer attendee questions quickly, brief suppliers properly, and trust the numbers after the event.
When the stack is fragmented, familiar problems appear:
- registration data has to be re-entered manually
- different teams work from different versions of attendee information
- check-in lists do not match late changes
- communications go out without the right segmentation
- sponsors and suppliers ask for updates that take too long to compile
- post-event reporting starts with cleanup instead of analysis
None of these issues require a huge enterprise environment to solve. They usually require clearer choices about what the core system needs to do, what can sit around it, and where data must stay consistent.
Start with the jobs that must work every time
Before comparing tools, define the operational jobs your stack must support.
For most small-to-medium events, that list is fairly stable:
- publish event information clearly
- register attendees and capture the right details
- take payments, if the event is paid
- send confirmations, updates, and reminders
- manage attendee records without duplicate admin
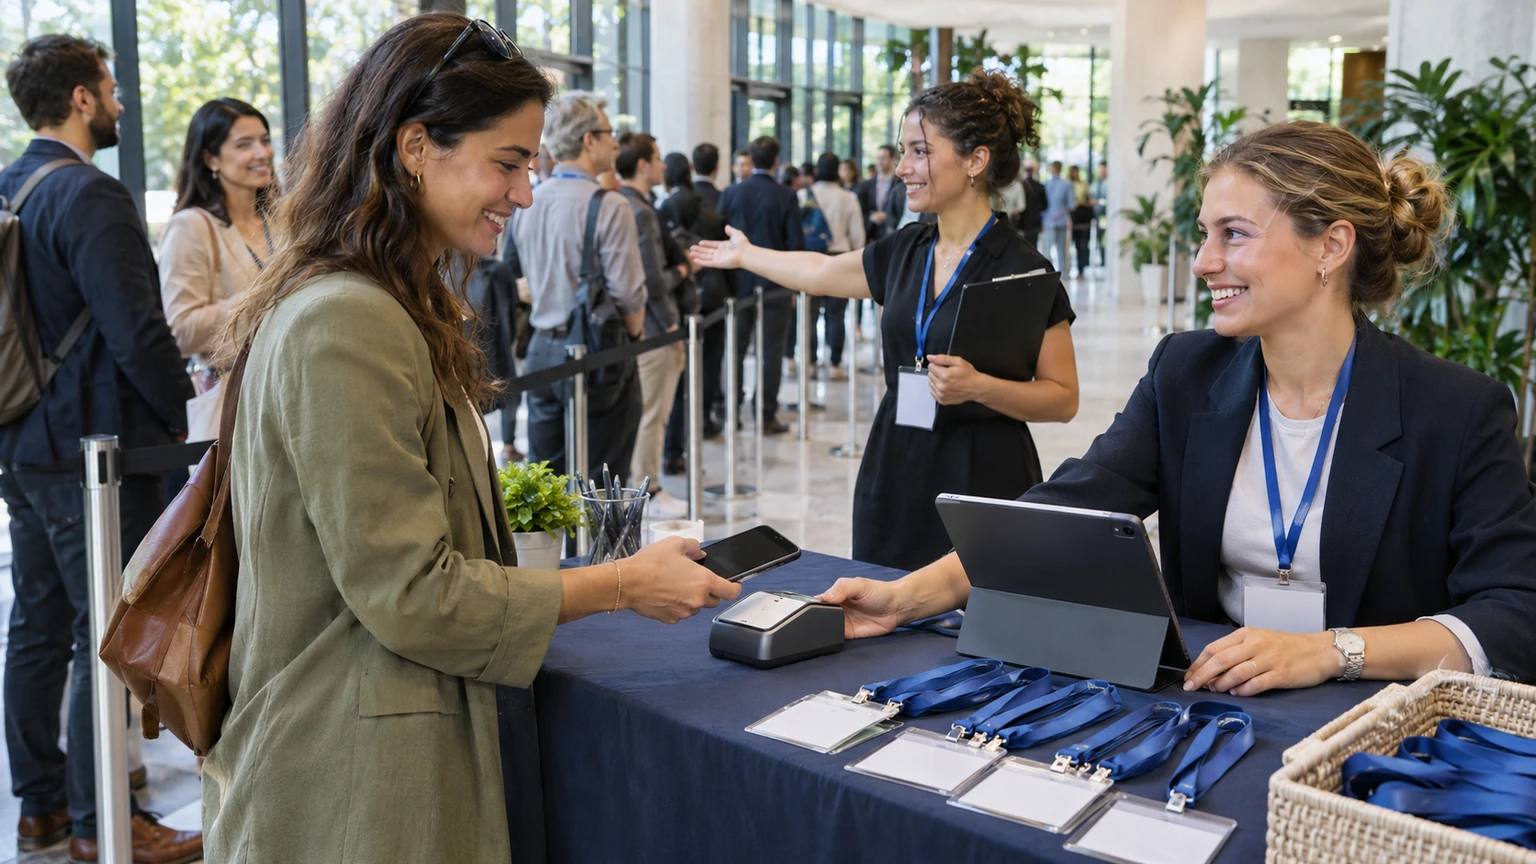
- support on-site check-in or access control
- give organisers usable reports before and after the event
Some events will also need speaker management, sponsor delivery, hosted meetings, badge printing, mobile engagement, or session scanning. Those are valid needs, but they should be added because the event model requires them, not because they look impressive in a demo.
Build around a clear system of record
The most important stack decision is often this: where does the authoritative attendee record live?
If your team cannot answer that cleanly, almost everything else becomes harder. Registration details, ticket status, category, special requirements, attendance changes, and communication history need a place that staff trust.
For many small-to-medium events, the safest operating model is to treat one core event system as the main source of truth for attendee data, then connect only the supporting tools that genuinely add value.
That helps reduce a common failure pattern: too many tools updating the same person record in slightly different ways.
If multiple systems can each become “the real list,” your team will eventually spend event week deciding which list to believe.
What a practical stack usually includes
The right combination varies by event format, but most teams benefit from thinking in layers rather than in a long shopping list.
1. Event hub
This is the central layer where the event is structured and attendee activity is anchored. In operational terms, this usually covers the event page, registration flow, attendee data, and key organiser controls.
This layer matters most because it shapes how reliably information moves through the rest of the event lifecycle.
2. Payments
If the event is ticketed, payments need to be dependable, explainable, and easy to reconcile. For free events, this layer may be minimal or unnecessary.
The practical question is not only whether payment can be accepted. It is whether the payment status stays aligned with the attendee record the team is using.
3. Communications
Attendee emails and operational updates often sit partly inside the event system and partly in wider marketing tools. That can work well, but only if responsibilities are clear.
Teams should know which messages are transactional, which are promotional, and which are operationally urgent.
4. On-site operations
This includes check-in, access validation, staffing workflows, badge processes if needed, and any live attendance tracking.
Small events may only need a simple, reliable check-in setup. Larger or more complex mid-sized events may need more structure around entry points, session access, or sponsor-related attendance proof.
5. Reporting and follow-up
Reporting should not be treated as something that happens only after the event. Organisers need usable visibility before, during, and after delivery.
Typical reporting needs include registrations, attendance status, ticket mix, no-show patterns, supplier lists, sponsor fulfilment evidence, and audience breakdowns.
Keep the stack proportionate to the event
One of the easiest mistakes is copying the stack of a much larger event.
A 300-person conference, a regional trade event, and a recurring member event do not need the same tooling model as a large-scale expo with multiple access rules, hosted buyer programmes, and a long sponsor inventory.
For smaller teams, every extra system creates real overhead:
- more setup time
- more training
- more handoff risk
- more chances for inconsistent data
- more cost to justify
That is why proportion matters. Simpler is not unsophisticated if it keeps the operation stable.
Choose integrations carefully
Integrations are useful when they remove repeat manual work or reduce the risk of errors. They are less useful when they connect tools that your team barely needs in the first place.
A practical test is to ask what the integration actually improves.
- Does it stop duplicate data entry?
- Does it reduce delay between registration and communication?
- Does it make on-site lists more accurate?
- Does it improve reporting enough to justify the added complexity?
- Does someone on the team understand how failures will be spotted and handled?
If the answer is vague, the integration may be adding architecture without adding operational value.
Where small-to-medium event teams should focus first
If the current stack feels messy, do not try to replace everything at once. Start with the points where operational friction is highest.
In many teams, that means reviewing these areas first:
- registration to attendee record: are sign-ups landing cleanly in one trusted place?
- attendee record to communication: can the right people receive the right updates without manual exports every time?
- attendee record to on-site delivery: do check-in staff see accurate, current information?
- attendee record to reporting: can organisers extract useful lists and outcomes without rebuilding the dataset manually?
That sequence usually exposes the real issue faster than a broad tool audit.
Questions worth asking before you add another tool
New tools can solve real problems, but they should survive a basic operational review.
- What exact job will this tool do?
- Who will own it internally?
- What data needs to move in or out of it?
- How often will staff use it?
- What process becomes easier because of it?
- What process becomes more complicated because of it?
- Can the team still operate if that tool fails on a live event day?
These questions are not anti-technology. They are how organisers stop a stack from growing faster than the event operation can support.
Where teams should be careful
There are a few recurring stack problems that are especially common in small-to-medium events.
Buying for edge cases
A team has one unusual sponsor request, one VIP workflow, or one difficult badge scenario, then builds the whole stack around that exception. Most of the event ends up carrying complexity it did not need.
Separating setup from delivery reality
A system can look good in procurement and still fail the event team operationally if the live workflow is awkward. The people checking in attendees, updating lists, and answering support messages should influence the stack design.
Overvaluing feature count
Feature volume is not the same as event readiness. If staff cannot use the setup confidently, the extra capability may never become real value.
Leaving reporting too late
Teams often notice data structure problems only when stakeholder reports are due. By then, repair work is slower and trust is lower.
What good looks like
A practical stack for a small-to-medium event usually feels calm rather than clever.
Attendee information is collected once and stays usable. The team knows where to check status. Operational emails go to the right groups. On-site staff are not improvising around stale spreadsheets. Suppliers can be briefed from reliable lists. Reporting does not depend on heroic manual cleanup.
That is what “bringing the event together” looks like in practice. Not a perfect all-in-one universe, but a setup where the important workflows hold together from launch to follow-up.
What this means for event teams
If you are reviewing your event stack, start with operational continuity, not software ambition.
Map the attendee journey, identify the records that must stay accurate, and reduce unnecessary handoffs. Keep one clear system of record. Add surrounding tools only when they solve a real delivery problem.
For small-to-medium events, the strongest stack is usually the one that lets a lean team stay organised, responsive, and accurate under pressure.
That is a more useful goal than having the longest list of platforms in the planning deck.